SENIOR DEVOPS & SERVICE RELIABILITY ENGINEER

Anil Kumar
Tangirala

CLOUD INFRASTRUCTURE · PLATFORM ENGINEERING · SRE

I design and build cloud infrastructure, Kubernetes platforms and delivery automation. I own the code, production rollout and reliability improvements that follow.
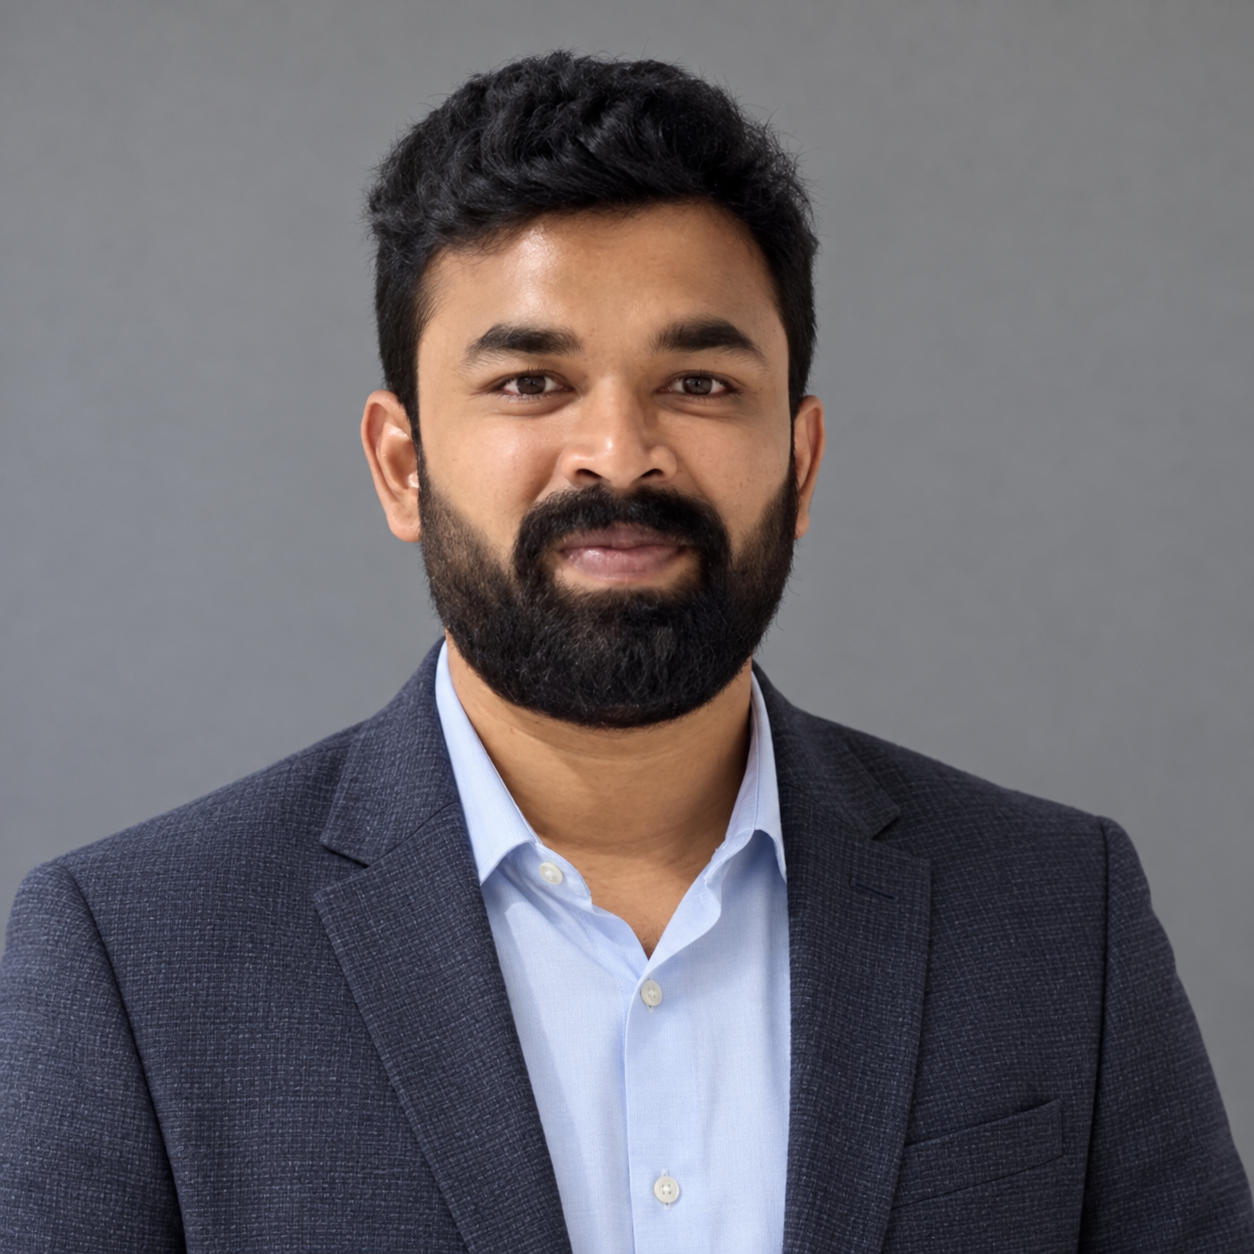
ORACLE · HYDERABAD, INDIAGITHUB ↗
INFRASTRUCTURE ENGINEERINGAKT
Anil Kumar Tangirala
Anil Kumar
Tangirala

Senior DevOps Engineer · Oracle

AWS · OCI · KUBERNETES · AUTOMATION

Cloud platforms.
Built and operated.

Eight years across SaaS, healthcare and e-commerce infrastructure.

My strongest platforms are AWS and OCI, complemented by hands-on Azure and GCP delivery. I develop infrastructure and deployment code, review production changes and lead migrations, upgrades and recovery.

At Oracle, I build reusable GitLab CI/CD workflows, Terraform and Python automation, release-testing tools and observability. I also develop custom Codex skills, MCP integrations and AI-assisted review workflows, with human approval retained for production changes.

ARTISTO / JENKINS

40% shorter pipelines

Re-engineered builds around Kubernetes-hosted agents and integrated code-quality and artifact tooling.

ARTISTO / INFRASTRUCTURE

50% faster deployment

Built reusable Terraform modules and Ansible workflows for provisioning and configuration.

ORACLE / ENGINEERING AUTOMATION

At least 75% less triage time

Built MCP telemetry correlation and custom Codex workflows to assemble evidence and diagnostic context.

Platform engineering
in practice.

Production work is separated from public reference projects. Each case explains the implementation, choices and limits.

DESIGN → PROVISION → REVIEW

Cloud architecture

Terraform, Python and Bash automation for repeatable provisioning, Kubernetes lifecycle management and controlled infrastructure changes.

AWS + OCIdeep focus
Terraformpersonal code ownership
Design, execution and results

Architecture and infrastructure as code

Develop Terraform, Python and Bash automation using OCI Resource Manager for multi-tenant platform provisioning and OKE lifecycle operations.

  • Review provider and environment assumptions, IAM boundaries and promotion criteria.
  • Use reusable modules, remote-state practices and configuration-drift checks.
  • Coordinate schema and architecture integrations with the relevant engineering owners.

Migration and workload evolution

Led EC2-to-EKS migration at Mobile Programming and an e-commerce VM-to-GKE migration at Artisto.

  • Standardize deployment configuration and workload management.
  • Work with developers on monolith-to-microservices deployment changes.
  • Operate Docker, ECS, bare-metal Kubernetes, AKS and OKE environments.

Security and cost controls

Infrastructure guardrails include IAM, Vault, AWS Secrets Manager, Azure Key Vault, AWS Config, Security Hub and WAF.

  • Implemented AWS Config-driven remediation for unused EC2 instances and unintended public network access at Artisto.
  • Use tagging and cost allocation to improve resource accountability.
  • Build Streamlit cloud-cost visibility alongside operational health.

Design decisions

  • Review the blast radius of replacement, network and IAM changes before execution.
  • Protect infrastructure state and secrets throughout the delivery lifecycle.
  • Cloud architecture decisions include operations access, recovery paths and ownership.

Infrastructure engineering across provisioning, migration, access controls and operational readiness.

CODE → QUALIFY → PROMOTE

Release engineering

Delivery spans code review, build quality, environment readiness, deployment qualification and a deliberate response when validation fails.

GitLabOracle + Mobile
GitHub ActionsArtisto
Design, execution and results

Reusable delivery systems

Build shared GitLab CI/CD templates with security scans, linting and compliance checks. Review infrastructure and pipeline code before production promotion.

  • OCI DevOps and Shepherd deployment and upgrade ownership.
  • Custom promotion gates validate integrations and configuration drift.
  • Prometheus and OpenTelemetry health signals validate releases and inform rollback.

Qualification and execution

Build Playwright Release Qualification automation for integrations and schema changes, coordinating defect resolution within approved change windows.

  • Review MOPs, SOPs, pipeline inputs and environment-specific assumptions.
  • Coordinate engineering, QA, infrastructure, security and support.
  • Preserve release evidence and distinguish qualification failures from infrastructure failures.

Earlier delivery engineering

Modernized Jenkins with containerized Kubernetes agents; integrated Maven, SonarQube, Nexus and JFrog Artifactory.

  • Kubernetes-hosted Jenkins agents cut pipeline execution time by 40% at Artisto.
  • GitHub Actions pipelines reduced deployment errors by 35% at Artisto.
  • Docker/Jenkins automation cut deployment time by 40% at Mobile Programming.

Design decisions

  • Separate read-only diagnosis from promotion, abort and retry operations.
  • An analysis-provider error is not the same as an observed application failure.
  • A rollback does not automatically undo schema or external-system side effects.

Release engineering across pipeline design, qualification, promotion and recovery.

SIGNAL → HYPOTHESIS → EVIDENCE

Reliability practice

Service symptoms, telemetry, recent changes and dependency behavior belong in one investigation—not separate dashboards.

−50%MTTD
−30%MTTR
Design, execution and results

Detection and investigation

Build Grafana SLO/SLI views, Streamlit uptime dashboards, OpenSearch/Kibana monitors and Slack-webhook notifications.

  • Correlate logs, service health, deployment context and database signals.
  • OpenSearch threshold monitoring reduced detection time by 45% within that alerting workflow; overall MTTD improved by 50%.
  • Lead incident, change and problem management with cross-stack root-cause investigation.

Resilience and real-time services

Standardize multi-region DR runbooks and failover tests for OCI storage and Oracle AI Autonomous Databases.

  • Validate replication, application recovery and operational procedures.
  • Deploy LiveKit and troubleshoot WebRTC; automate jitter and packet-loss analysis.
  • Investigate IoT and real-time connectivity across carrier and satellite networks.

Operational judgment

Missing telemetry is unknown—not healthy. Temporal correlation is a hypothesis—not proof of root cause.

  • Record scope, observation time, owner and next falsification check.
  • Keep generated explanations separate from observed facts.
  • Verify recovery through application behavior, not backup status alone.

Design decisions

  • Paired SLO windows distinguish persistent burn from a short spike.
  • Use evidence and known failure signatures to narrow investigation.
  • Document unknown impact and missing evidence explicitly.

Oracle outcomes: incident SLA compliance, detection and resolution are separate measures, not availability guarantees. The interactive SLO example uses synthetic counters.

ORIGINAL PROJECT / PYTHON

SignalDesk

A runnable incident workspace that separates deterministic findings, retrieved runbooks, uncertainty and optional LLM synthesis.

14bounded workflows
Testeddomain and transport behavior
Design, execution and results

Incident intelligence

Evidence preflight, known-issue matching, incident triage, SLO analysis, UTC timelines and log-pattern grouping.

  • Missing history is not treated as no known issue; closed issue matches are retained.
  • Paired 5m/1h and 30m/6h windows calculate request-based burn rates.
  • Deployment timing is reported as correlation without inferring causation.

Team context and engineering tools

Ownership resolution, dependency impact, runbook Q&A, RCA hypotheses, code review, code-fix proposals, test plans and postmortem scaffolding.

  • Dependency traversal protects against cycles and reports unknown ownership.
  • Python AST checks identify illustrative reliability patterns such as missing request timeouts.
  • Code-fix output is an unexecuted diff; it does not change source files.

Retrieval and transport architecture

Validate JSON → curated facts → bounded knowledge loading → BM25 retrieval → optional model → citation-ID validation.

  • 220-word chunks with 40-word overlap; optional embedding retrieval uses reciprocal-rank fusion.
  • Remote model transport requires HTTPS, rejects URL credentials and redirects, and bounds response size.
  • Offline operation makes no model call; hosted synthesis requires explicit configuration.

Design decisions

  • Rules calculate; retrieval supplies context; the model explains.
  • Citation-ID validity does not prove the source supports the model interpretation.
  • 14 workflows are bounded tools, not 14 autonomous agents.

Reference implementation using synthetic data. No production deployment, live-model evaluation, SSO or multi-tenant access-control claim.

ORIGINAL PROJECT / STATIC REVIEW

Platform Readiness RAG

Inspect exported Kubernetes workloads against explicit starter standards, then retrieve the policy context behind each finding.

4supported workload kinds
Testedresource-level checks
Design, execution and results

What the reviewer inspects

Deployment, StatefulSet, DaemonSet and Pod exports. Resource identifiers stay attached to individual findings.

  • Replica count, CPU/memory requests and limits, readiness and liveness probes.
  • Missing, implicit-latest or explicit-latest image tags.
  • Privileged execution, non-root settings, privilege escalation and host network/PID access.

Scope and data handling

The reviewer lists skipped resource kinds and never mistakes unsupported objects for passed checks.

  • Container environment values are omitted from curated model facts.
  • Pod security defaults and container overrides are resolved explicitly.
  • No kubectl command or admission-policy change is performed.

Design tradeoffs

Deterministic starter checks provide resource-level evidence; optional RAG explains the relevant platform policy.

  • CPU-limit and probe exceptions still require workload-specific engineering judgment.
  • HPA, PDB, NetworkPolicy, Jobs and init-container coverage are outside v0.1.
  • A passing starter check is not production-readiness certification.

Design decisions

  • Report findings at the exact workload/container, not as a generic checklist.
  • Treat unsupported scope as a limitation visible to the reviewer.
  • Keep runtime health separate from manifest quality.

Reference implementation using static exports and synthetic fixtures; no live-cluster access or admission enforcement.

ORIGINAL PROJECT / TERRAFORM

Change Risk RAG

Identify destructive changes, internet exposure, protection removal and uncertainty without forwarding raw Terraform values to a model.

Testedplan-risk behavior
Human reviewalways required
Design, execution and results

Risk signals

Recognize both Terraform replacement orders, deletion, forget actions and stateful-resource risks.

  • Stateful replacement or removal of deletion protection triggers critical review.
  • Detect newly introduced IPv4/IPv6 world-wide ingress in supported AWS shapes.
  • Report nested unknown values, errored plans and incomplete plans explicitly.

Data minimization by design

Reports contain resource addresses, action lists and curated findings—not raw before/after values, variables or outputs.

  • No-op and data-source reads do not inflate the change count.
  • Public egress is not mislabeled as new ingress.
  • The CLI only reads a local plan export; it never runs Terraform plan or apply.

Review, not prediction

Retrieved rollout and recovery guidance helps a reviewer decide what evidence is required before promotion.

  • Risk rating is a documented heuristic, not a failure probability.
  • Provider-specific checks are limited; arbitrary IAM semantics are not fully modeled.
  • Human approval remains necessary even when no rules trigger.

Design decisions

  • Reduce data exposure before invoking a model.
  • Surface unknown values instead of interpreting them as safe defaults.
  • Separate backup/rollback prerequisites from the authority to apply a change.

Reference implementation with synthetic fixtures; provider coverage is limited and the heuristic does not prove a change safe.

12 UPSTREAM PROJECTS / ORIGINAL GUIDANCE

Operations field guides

My public collection preserves upstream authorship and licenses. My contribution is practical operations documentation: review questions, diagnostic checks and failure-mode guidance.

12operations guides
Upstreamcode attribution retained
Design, execution and results

K8sGPT: analysis before explanation

Verify context, namespace and RBAC; inspect deterministic findings before requesting an LLM explanation. Treat no findings as a scope question, not a health guarantee.

EKS: module change review

Separate local validation from cloud-backed planning. Review endpoint access, IAM, node draining, networking, add-on compatibility and state recovery.

Argo Rollouts: classify the pause

Distinguish manual pause, failed/errored/inconclusive analysis and workload readiness. Inspect traffic routing before promoting or aborting.

Velero: recovery evidence

A completed backup is not restore proof. Review resource/storage coverage, consistency, encryption, dependencies and retention; verify recovery through application behavior.

Design decisions

  • Read-only diagnostic access is not authority to mutate production.
  • Keep upstream implementation credit separate from original operational guidance.
  • Avoid invented recovery objectives or promises of autonomous remediation.

Upstream software with my operations documentation additions. Upstream authorship and licenses are retained.

Multi-region
production ownership.

Infrastructure automation, release engineering and reliability across ECP, ECP-RT, OSDMC and ICON.

ORACLE / PRODUCTION

ECP

Cloud infrastructure and IoT

Develop Terraform, Python and Bash provisioning automation and OKE lifecycle workflows. Deploy LiveKit and investigate WebRTC, jitter and packet loss across Starlink, AT&T and Vodafone connectivity.

ORACLE / PRODUCTION

ECP-RT

Production delivery and real-time services

Execute platform deployments and upgrades, build Playwright-based qualification and validate post-deployment behavior. Resolve infrastructure failures and coordinate application fixes within approved change windows.

ORACLE / PRODUCTION

OSDMC

Platform lifecycle and tenant operations

Develop infrastructure and delivery automation within the shared platform remit. Validate tenant-capacity changes, service health and identity integrations before and after production changes.

ORACLE / PRODUCTION

ICON

Infrastructure and deployment engineering

Build and review Terraform, Python, Bash and GitLab CI/CD workflows for provisioning and OKE lifecycle operations within the multi-region, multi-tenant platform environment.

04 / EXPERIENCE

From delivery systems
to platform ownership.

Hands-on engineering across three employers.

Full résumé ↗
FEB 2025 — PRESENT · HYDERABAD

Oracle India

Senior DevOps Engineer (SRE). Design and implement infrastructure automation, reusable delivery pipelines and production upgrades across multi-region, multi-tenant platforms.

  • Terraform, Python, Bash and OCI Resource Manager for provisioning and OKE lifecycle management.
  • OCI DevOps and Shepherd delivery, GitLab templates and promotion gates.
  • SLO/SLI monitoring, MCP correlation, AI code review and human-approved production decisions.
MAY 2023 — FEB 2025 · BANGALORE

Mobile Programming India

DevOps Engineer. AWS and OCI healthcare platform delivery, EC2-to-EKS migration and standardized OKE rollout checks.

  • GitLab CI/CD builds, vulnerability scans and microservice deployments.
  • Terraform and Ansible provisioning, configuration, updates and bulk patching.
  • Bash and CI/CD automation reduced manual intervention by 50%; Docker and Jenkins-driven Kubernetes delivery cut deployment time by 40%.
OCT 2018 — MAY 2023 · VIZAG

Artisto Technologies

DevOps Engineer across cloud, platform and infrastructure. AWS foundation with Azure and GCP engagements; build automation, containers and e-commerce migration.

  • Terraform modules and Ansible reduced deployment time by 50%.
  • GitHub Actions, Jenkins Kubernetes agents, Argo CD and Azure DevOps workflows.
  • Healthcare routing and availability, observability, security controls and Artrya infrastructure.

Architecture, code
and production.

CLOUD & INFRASTRUCTURE

AWS and OCI

Deep production experience, with additional Azure and GCP engagements. Terraform · Ansible · CloudFormation · AWS CDK

CONTAINERS & SYSTEMS

Kubernetes and Linux

EKS · OKE · AKS · GKE · Bare metal · Docker · Helm · Istio

DELIVERY & TESTING

Reusable pipelines

GitLab CI/CD · Jenkins · GitHub Actions · Argo CD · OCI DevOps · Shepherd · Playwright · SonarQube

OBSERVABILITY

Service and cost visibility

Prometheus · Grafana · OpenSearch/Kibana · ELK · OpenTelemetry · Datadog · New Relic · Streamlit

PROGRAMMING & AI

Engineering automation

Python · Bash · Go · PowerShell · Custom Codex skills · MCP servers · AI code review

DATA & SECURITY

Reliable integrations

Oracle Database · MySQL/Aurora · SQL Server · Kafka · Vault · IAM · AWS Config · LiveKit · WebRTC

CONTACT

Anil Kumar
Tangirala

anilkumartangirala7@gmail.com ↗